Skip to forum
Notifications
Clear all

Alternatives to ICM?

160 Posts
12 Users
0 Reactions
25.4 K Views

Originally posted by muebarek
What happens in the game of these N perfect players when they play a hand is that some players win some chips and some other stacks lose chips (of course the total number of chips is conserved). But on average neither one will have a change in his stack since TEQ is a martingale.

While the average equity of each player will not change, the average number of chips in each stack may change.

Let us imagine that you have a freezeout for 2 player from tossing an unfair coin which favors player A 60% of the time, wagering 1 chip at a time. The players start with 3 chips each.

A's winning chances as a function of chip count
6: 100%
5: 95.2%
4: 88.0%
3: 77.1%
2: 60.9%
1: 36.5%
0: 0%

For example, 77.1% equals the weighted average of 88.0% and 60.9%, weighting the greater value 60% and the lesser 40%. 3 chips is not the weighted average 60% x 4 + 40% x 2 = 3.2, so player A expects to gain 0.2 chips per toss.

Similarly, the players may expect to gain or lose chips, but on average their tournament equities stay the same. With no skill advantage, but stacks of 5-10-15, imagine that the only possible results of the hand are 0-15-15 and 10-5-15, but these happen with probability 60% and 40%, respectively. Then the shortest stack will lose 1 chip on average, and the equity of 5-10-15 must be the weighted average of his equity in 0-15-15 and 10-5-15.

The ICM predicts finishing probabilities for each position, not just the total equity. One of the properties of the ICM is that each player wins the tournament with probability proportional to his stack. This means the players do not gain or lose chips on average throughout the tournament. In practice, this is not plausible. In many situations, the chip leader can accumulate chips on average.

There is a different model, diffusion, which assumes that the chips are moved fairly until players are eliminated. This sounds similar to what you suggest. This builds in an assumption that players win the tournament with probability proportional to their stacks, and it is not as easy to compute as the ICM. A minor exception is with 3 players, since then the Riemann map to the disk is conformal and preserves the measure on continuous diffusion paths, and you can work with the explicit Riemann map. Chris Ferguson's father wrote about this in an unpublished paper. This does not extend to more players.

Reply
Quote
muebarek
Joined: 31.07.2008
Oldschool Grinder

Originally posted by pzhon
While the average equity of each player will not change, the average number of chips in each stack may change.
[...]
The ICM predicts finishing probabilities for each position, not just the total equity. One of the properties of the ICM is that each player wins the tournament with probability proportional to his stack. This means the players do not gain or lose chips on average throughout the tournament. In practice, this is not plausible. In many situations, the chip leader can accumulate chips on average.

Hmm. I have to admit this is a valid objection. The model calculates finishing probabilities as well of course since it just counts of often a player busts in which place, but after your explanation I got aware of the fact (or should I say re-aware - the funny thing is, I mentioned this in a skype discussion with jbpatzer some days ago) that my model has about the same flaws as ICM (this is probably why it gives quite similar values).
For example, its finishing place probabilities do (as ICM's) not depend on the payout structure while the nash ranges obviously do - but this will yield a payout dependence in the finishing probabilties when actually shoving/calling with these ranges. This is exactly the inconsistence jbpatzer is measuring and he'd measure it in a similar way with my model.

Originally posted by pzhon
There is a different model, diffusion, which assumes that the chips are moved fairly until players are eliminated. This sounds similar to what you suggest. This builds in an assumption that players win the tournament with probability proportional to their stacks, and it is not as easy to compute as the ICM. A minor exception is with 3 players, since then the Riemann map to the disk is conformal and preserves the measure on continuous diffusion paths, and you can work with the explicit Riemann map. Chris Ferguson's father wrote about this in an unpublished paper. This does not extend to more players.
This is interesting. Do you have any links where I can find some information on this or any scientific paper on tournament equity? I never heard of this diffusion thing though I was actually looking for alternative TEQ-models when I started MTTs since ICM for more than ~12 payout places isn't really computable in decent time and I'm not too happy using cEV on final 2 tables (not that diffusion could help me there if you say it computes slower)


Reply
Quote

See this paper by Chris Ferguson and Thomas Ferguson, who is a mathematician at UCLA: "The Endgame in Poker."

There was some past comparison between the ICM and diffusion in the twoplustwo forums, maybe around 2004 by dethgrind or eastbay. ICM worked well enough that people lost interest in diffusion, but it is possible that since edges are smaller now, a significant benefit can be gained by looking at alternatives.


Reply
Quote
LgWz
Joined: 26.05.2007
BlackMember

The diffusion model is briefly discussed (and compared to ICM) in Kill Everyone iirc.


Reply
Quote
jbpatzer Topic starter
jbpatzer
Joined: 23.11.2009
Oldschool Grinder

So. Some results. I did 11 simulations and, since order doesn't matter with randomized positions, here's the space covered in terms of the first two stack sizes (s3 = 30 - s1 - s2 in this case).

Differences from ICM below

18 8 4 0.0240 -0.0020 -0.0220
12 9 9 0.0100 -0.0050 -0.0050
15 7.5 7.5 0.0240 -0.0120 -0.0120
20 5 5 0.0250 -0.0125 -0.0125
24 3 3 0.0100 -0.0050 -0.0050
11 11 8 0.0020 0.0020 -0.0040
13.5 13.5 3 0.0100 0.0100 -0.0200
12 12 6 0.0080 0.0080 -0.0160
12.5 10 7.5 0.0150 -0.0040 -0.0110
15 10 5 0.0210 -0.0020 -0.0190
17.5 10 2.5 0.0150 -0.0020 -0.0130
18.5 10 1.5 0.011 -0.003 -0.008
27 1.5 1.5 0.003 -0.001 -0.002

I can plot these in 3D as points and then zoom around them in MATLAB, but it just looks like a big splodge when I try to make something to post here.

This is quite interesting though. This is the difference between ICM predicted and actual TEQ when two of the stacks are equal, plotted against the size of the two equal stacks.

And this is the TEQ difference when the middle stack has 10BB.


Reply
Quote
jbpatzer Topic starter
jbpatzer
Joined: 23.11.2009
Oldschool Grinder

Added a couple of extra data points to the post above.


Reply
Quote
jbpatzer Topic starter
jbpatzer
Joined: 23.11.2009
Oldschool Grinder
muebarek
Joined: 31.07.2008
Oldschool Grinder

Originally posted by jbpatzer
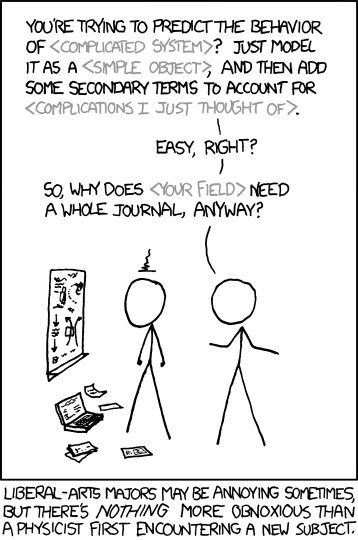
Oh shit! Is this us?

oops. busted!


Reply
Quote

Originally posted by jbpatzer
Oh shit! Is this us?

:heart: XKCD


Reply
Quote
jbpatzer Topic starter
jbpatzer
Joined: 23.11.2009
Oldschool Grinder

I've been having a bit of a think, and here's what I came up with.

ICM assigns probabilities of finishing first in proportion to stack size, and then works backwards, using current stack sizes to determine proportions of second and third place finishes. One problem with this is that the game works in the other direction. If we knew the probabilities of finishing third, we could then assign the chips of the third placed player to the other players in proportion to the size of their stacks, and continue.

My first thought was that instead of making the probability that the ith player finishes first s_i/(s_1+s_2+s_3), we could make his probability of finishing third (1 - s_i/(s_1+s_2+s_3)). This sounds good, but the probabilities of the three players finishing third then sum to 2, which is not entirely satisfactory! It did however start me thinking.

If you take the stack sizes and plug them into ICM, it will give you probabilities of finishing third. If you take these probabilities, and plug them into a model as described above, you can work in the other direction and find probabilities of finishing first. You can then do this repeatedly until the answers converge (the probabilities calculated stop changing). Of course, I don't (yet?) have a proof that this process necessarily converges, but I've coded it up and, in practice for every set of stack sizes I've tried, it does converge, and very quickly. And even better, this assigns higher TEQ to big stacks than ICM does, and lower TEQ to small stacks.

I've coded this up and am running a simulation with initial stacks [5 10 15]. It runs rather more slowly than ICM, because of the iteration that now underlies each ICM+ calculation. It seems to take only about 4 iterations at most to converge, but there is a noticeable loss of performance. Some sort of look up table to allow the other iteration that determines the Nash ranges to start closer to equilibrium would probably help.

Anyway, I'll report back with some results when I have them. Even if this approach doesn't prove to be better than ICM, I think there's the kernel of an idea here that might be a basis for something better.


Reply
Quote
muebarek
Joined: 31.07.2008
Oldschool Grinder

First of all I have to say I like the way you approached this. Thinking about what’s really going on in tournaments will imo always be more promising than just trying to find a function which fits the results well.

Originally posted by jbpatzer
If we knew the probabilities of finishing third, we could then assign the chips of the third placed player to the other players in proportion to the size of their stacks, and continue.
[…]
And even better, this assigns higher TEQ to big stacks than ICM does, and lower TEQ to small stacks.

After reading the first quoted sentence I was kind of waiting for the second one to come. By assigning the chips of the third to the other players in proportion to the size of their stacks you’re automatically implementing an edge for the bigstacks since you give them a “higher winrate” in 3handed play. This is contrary to ICM where the chips of the first are simply “removed” which is (as you correctly mentioned) not what’s really going on.
But this split up rule also seems a bit arbitrary to me (someone may come and suggest to split them up evenly for example[which i think would be bad for various reasons]) and it will have its weaknesses since extreme short stacks will probably tend to suffer way more than the 5bb-stacks which seemed to have the biggest TEQ-loss in your results.

Nonetheless, I think it is definitely worth a try, because giving an edge to the bigstacks is somehow what we want to achieve. I just found it worth mentioning where this effect comes from in your model.


Reply
Quote
nibbana
Joined: 05.12.2009
Oldschool Grinder

Originally posted by jbpatzer
If you take the stack sizes and plug them into ICM, it will give you probabilities of finishing third. If you take these probabilities, and plug them into a model as described above, you can work in the other direction and find probabilities of finishing first

Aren't you then taking the unsatisfactory results that ICM comes up with as the foundation for the new method ? Sorry if this sounds dumb, please humour me, it's about the first thing in 3 pages that I vaguely understand.


Reply
Quote
jbpatzer Topic starter
jbpatzer
Joined: 23.11.2009
Oldschool Grinder

Originally posted by nibbana

Originally posted by jbpatzer
If you take the stack sizes and plug them into ICM, it will give you probabilities of finishing third. If you take these probabilities, and plug them into a model as described above, you can work in the other direction and find probabilities of finishing first

Aren't you then taking the unsatisfactory results that ICM comes up with as the foundation for the new method ? Sorry if this sounds dumb, please humour me, it's about the first thing in 3 pages that I vaguely understand.

You're right, but it's only using half of the old ICM idea. ICM uses the stack sizes to divide up first place, then works backwards. What I'm doing is dividing up first place, working backwards using the ICM method to divide up third place, and then working forwards in what seems like a sensible way to find the division of first place. And repeat until the answers are consistent. You'd really like to start with a sensible division of third place, work forwards, and stop there, but it's not obvious a priori how to divide up third place. ICM's division of first place by stack size is clearly wrong, and this replaces it with something else, i.e. not necessarily just by stack size.


Reply
Quote
jbpatzer Topic starter
jbpatzer
Joined: 23.11.2009
Oldschool Grinder

Originally posted by muebarek

But this split up rule also seems a bit arbitrary to me (someone may come and suggest to split them up evenly for example[which i think would be bad for various reasons])

They can of course be split up in whatever proportion we like. My original thought was to split them up evenly, but I thought that the big stack is more likely to get the third place's chips. However, you might argue that, as the short stack is less risk averse against the medium stack than against the big stack, this biases things towards the medium stack. I can try this too. I think the point is that we have a parameter that we can try to model based on poker knowledge rather than simply curve fitting, which has to be good.


Reply
Quote
muebarek
Joined: 31.07.2008
Oldschool Grinder

Good point. Imo this is where the results of your simulations become relevant. They might give us a direction for getting this right! To avoid the same inconsistency as of ICM, we'll have to have the split up dependent on the stack distribution and the payout structure, favoring the bigstacks more with increasing second price money.


Reply
Quote
JustgAMblin
Joined: 09.01.2007
Elite Grinder
jbpatzer Topic starter
jbpatzer
Joined: 23.11.2009
Oldschool Grinder

Originally posted by JustgAMblin
.

Good point


Reply
Quote
jbpatzer Topic starter
jbpatzer
Joined: 23.11.2009
Oldschool Grinder

ICM

ICM+ (EDIT: It should say 'ICM+ prediction' below.)

A significant improvement I think! I'm now going to play off two ICM players against an ICM+ player and cross my fingers!

I had to sit in a traffic jam on the way into work this morning for about two hours (Aaaaaaargh!), during which time I used a sophisticated mathematical technique to think about this problem - a technique us pros call 'counting'. For a three handed bubble, using this new ICM+ model, we have two unknown probabilities of players 1 and 2 finishing first (probabilities sum to one, so we won't worry about player 3), and two unknown probabilities of players 1 and 2 finishing third, for a total of four unknowns. It would be nice if we also had four equations to determine these unknowns. Well, the probabilities of players 1 and 2 finishing first, second or third must sum to one (2 equations), and their probabilities of finishing second as calculated by the ICM (first -> second -> third) method should equal those calculated by our new method (third -> second -> first). That's two more equations. Bingo! Number of unknowns = number of equations. In fact, they're linear equations, so the iterative method of calculating the probabilities isn't really necessary, and we could just write down the probabilities in terms of the stack sizes.

But, and this is a big but...

(Sorry couldn't resist that. I love the fact that I can do stuff here that I can't do in a scientific paper!).

If there are N>3 players, you quickly realize (counting!) that there are more equations than unknowns. This doesn't mean that you can't try the same iterative method, but (i) you don't necessarily get convergence of the probabilities of finishing first and Nth (this just needs testing), and (ii) even if you do get convergence, although the first place and Nth place probabilities have converged, it's almost certain that the intermediate probabilities that you get from ICM and ICM+ will be different. The good news is that I don't think that (ii) is an obstacle. The probabilities calculated from ICM+ (Nth-> (N-1)th -> ... -> 1st) are based on a division of stacks that makes sense, and so I would go with these. But if the iteration doesn't converge, or at least may not converge in some cases, there's some more headscratching to be done.

In the meantime, I won't look a gift horse in the mouth, and will just get on and and simulate more three handed bubbles.


Reply
Quote
jbpatzer Topic starter
jbpatzer
Joined: 23.11.2009
Oldschool Grinder

Quick update. I'm running ICM v ICM+ & ICM+, and ICM+ v ICM & ICM atm. Any differences seem very small, and I think I need to simulate more than 10K tourneys to establish a statistically significant difference between ICM & ICM+. If you're holding your breath waiting for the results, I would recommend you exhale now.


Reply
Quote

You may want to use an unbiased variance reduction technique similar to those used to speed up backgammon rollouts. Construct an unbiased martingale (for each player) which is highly correlated to the luck, and subtract this off. Since the martingale has average value 0, this does not affect the asymptote, but you might be able to reduce the variance significantly.

For example, suppose a player with 10 chips gets all-in against a player with 15 chips with 60% equity. Estimate the equity of each player when the player with 10 chips wins, and also when the player with 10 chips loses. Using the ICM is fine. Suppose a win is worth A for a player according to the ICM, while a loss is worth B. The weighted average is 60% A + 40% B, and a win is lucky by 40% (A-B) while a loss is lucky by 60% (B-A). Add the luck estimate to a running total for that player, and subtract the total luck from the results at the end.

It is more complicated, but possible in your model to create an unbiased estimate of the luck from getting called or not, and by which hand.

I think implementing both might speed up the convergence by more than a factor of 10.


Reply
Quote
Share: